Gemini 4 Argon API Cost Guide: Cache Costs, DeepSeek Rates and ROI
Check Gemini 4 Argon API/cache prices and the Dec 2026 change. Use the calculator for token estimates, and compare DeepSeek without treating price as task ROI.
On this page
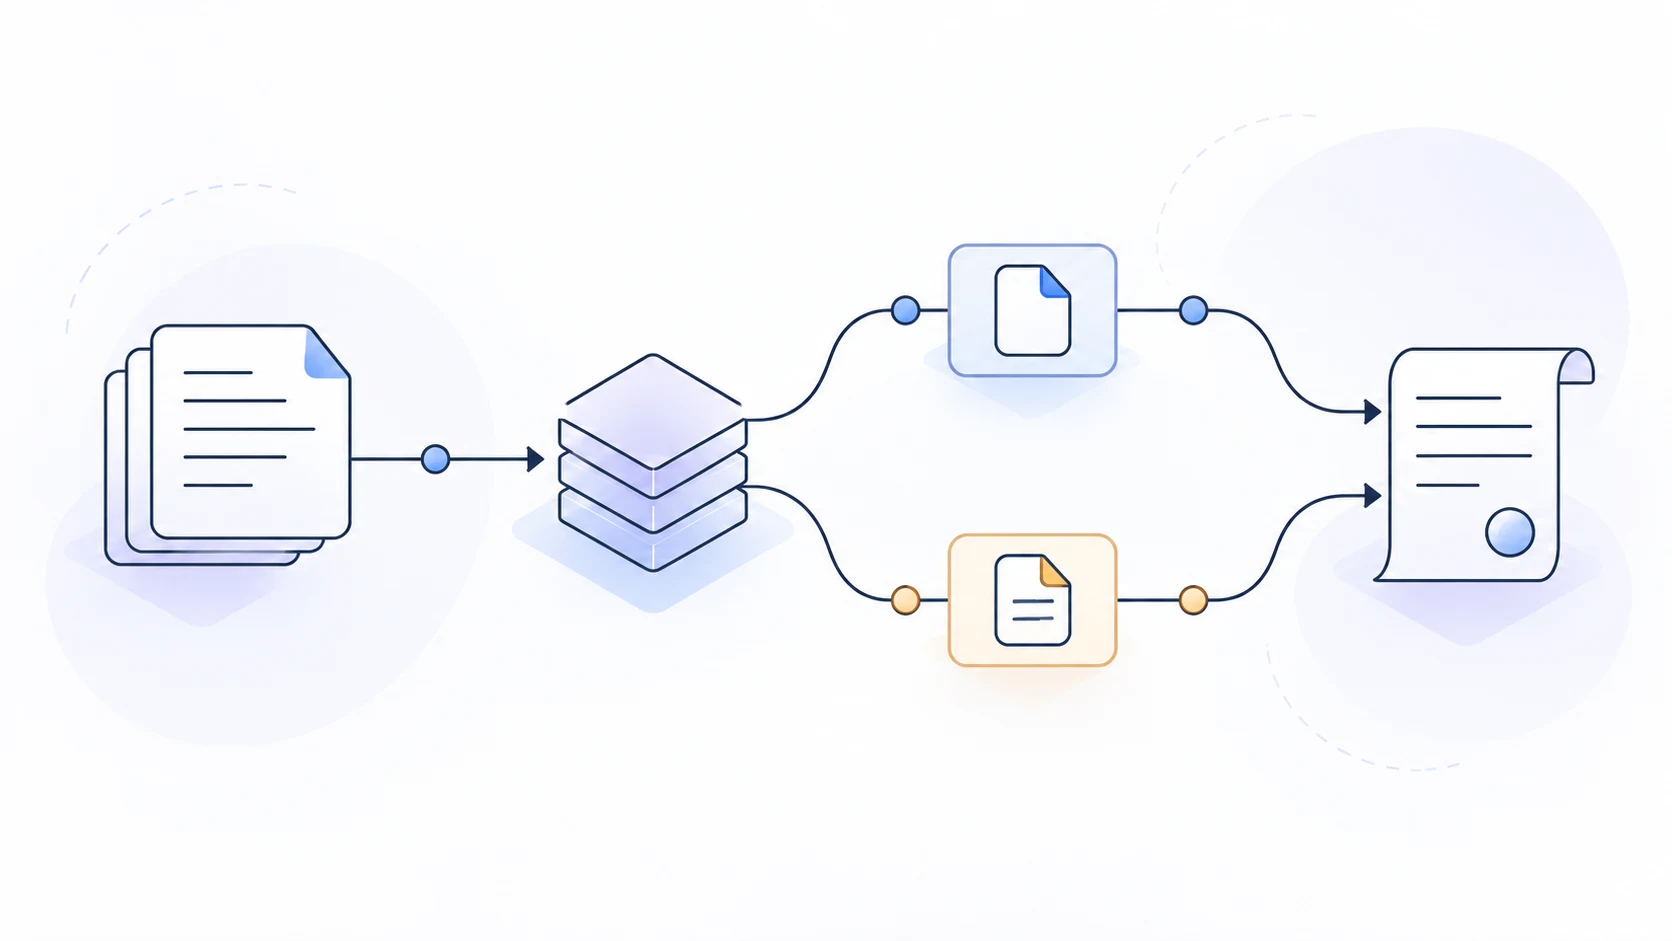
Gemini 4 Argon’s API price includes a cache-hit discount, but a request is not guaranteed to hit the cache. To estimate enterprise spend, separate ordinary input, cached input and output. Add retries, tool calls and human review as separate costs. This article uses one shared token-volume assumption to compare public rates for Gemini 4 Argon and DeepSeek V4.1 Flash.
Prices in this article were checked on October 14, 2026. Model availability and rates can change, so check each provider’s pricing page before preparing a budget. The examples are calculations from published token prices, not API tests or customer bills from this site.
Quick summary
Gemini 4 Argon’s introductory API rates are $2/M input and $10/M output, with cached input at $0.10/M through November 30, 2026. To compare it with DeepSeek V4.1 Flash, keep each provider’s rates, cache conditions and rate windows visible before estimating accepted-task cost.
Why token price is not ROI
Token rates cover only part of a bill. Input, output and thinking-token volumes, cache hits, retries and human review time all affect the final cost. A calculator should show a reproducible scenario, not turn a lower unit price into a claimed business return.
Key takeaways
- Gemini 4 Argon’s introductory price ends on November 30, 2026; new rates start December 1.
- The 95% discount applies only to cached input that actually hits; the selected hit rate is an assumption.
- DeepSeek V4.1 Flash API rates vary between peak and off-peak windows.
- Equal token volumes isolate price differences; they do not prove equal task cost or output quality.
Gemini 4 Argon API prices change in December 2026
Google’s Gemini API documentation lists an introductory price of $2.00 per million input tokens and $10.00 per million output tokens. Cached input tokens cost $0.10 per million. The introductory rates run through November 30, 2026. On December 1, input changes to $4.00, output to $20.00 and cached input to $0.20 per million tokens. Google Gemini 4 Argon pricing
Output pricing includes thinking tokens. A budget that counts only the answer visible to a user can understate output usage. Google also states that Gemini 4 Argon is not available on the Gemini API Free tier or the Google AI Pro API plan. Access through a Gemini app subscription is a separate product and billing route; do not treat the two as equivalent. Model and API pricing documentation
The 95% discount applies only to cached input hits
Gemini 4 Argon uses implicit context caching. Google says prompts of at least 4,096 tokens participate in the caching mechanism; the 95% discount applies only to input tokens that actually hit the cache. Argon does not support creating explicit cache objects, so the hit rate is not a guaranteed service setting. Gemini API caching and migration notes
That is different from billing every input token at $0.10 per million. A stable system prompt, repeated document prefix or reusable context may be cached. New or changing text may still be billed at the standard input rate. Check provider usage fields to see what was actually cached.
Estimate a bill with one shared token assumption
Consider 50M input tokens, a 70% cache-hit rate and 10M output tokens. At Gemini’s introductory prices, 35M cached input tokens at $0.10/M cost $3.50. The remaining 15M input tokens at $2/M cost $30. The 10M output tokens at $10/M cost $100. The token subtotal is $133.50.
| Published rate snapshot | Uncached input | Cached input | Output | Token subtotal |
|---|---|---|---|---|
| Gemini Argon introductory | $30.00 | $3.50 | $100.00 | $133.50 |
| Gemini Argon from Dec 1, 2026 | $60.00 | $7.00 | $200.00 | $267.00 |
| DeepSeek V4.1 Flash peak | $4.50 | $0.21 | $12.00 | $16.71 |
| DeepSeek V4.1 Flash off-peak | $2.25 | $0.105 | $6.00 | $8.355 (about $8.36) |
Google and DeepSeek publish these prices separately. DeepSeek’s API model ID is deepseek-flash. Its input and output rates vary by peak and off-peak hours; off-peak rates are half the peak rates. DeepSeek API models and prices
This example assumes both models consume the same number of tokens and use the same cache-hit ratio. It compares listed input, cached-input and output prices only. It does not compare answer quality, completion rate, latency, retries or human-review effort. A token-price difference alone is not a cost-per-task ROI result.
Benchmarks add context, but do not replace a workload comparison
Google DeepMind’s model card reports Gemini 4 Argon at 68.9% on Vals Index, 65.4% on Vals Finance Agent v2 and 51.3% on AutomationBench. DeepSeek’s model card reports 54.8 Pass@1 on AutomationBench for V4.1 Flash. These are results published by two providers. They are not a controlled side-by-side run performed by this site, so do not use the difference alone to rank your workflow. Google DeepMind model card, DeepSeek V4.1 Flash report
A more useful ROI measure is cost per accepted task. Add token spend, tool and serving charges, retries and human review time, then divide by the number of tasks that pass the agreed checks. A cheaper model can cost more overall if failed runs need repeated retries or manual repair. A more expensive model also needs evidence that it reduces failure or review effort.
Estimate cache use and price changes with the calculator
The calculator below changes input volume, cache-hit rate, output volume and the DeepSeek rate window. It also switches Gemini between introductory and regular rates. The default values match the 50M / 70% / 10M example above. It estimates token charges only; tools, platform fees, taxes, retries and human review are excluded.
Check the DSH provider catalog before adding Argon
DSH’s built-in Google provider uses Google’s native Generative AI protocol. Start with the Google provider setup guide, then check whether your installed version’s model picker lists gemini-4-argon. A model being available through Google’s API does not mean every DSH version has already added it to its installed catalog.
If Argon is missing, check the DSH version and model catalog first. Do not put Google’s native API into a custom provider form for OpenAI Completions, OpenAI Responses or Anthropic Messages; those are different protocols and a model ID cannot replace an adapter.
Common questions
Will Gemini 4 Argon cached input always cost $0.10 per million tokens?
No. $0.10/M is the introductory cached-input rate through November 30, 2026. Google lists $0.20/M from December 1. Both prices apply only to input tokens that hit the cache.
Does the 95% cache discount guarantee a hit on every request?
No. Google uses implicit caching. Prompts of at least 4,096 tokens enter the caching mechanism, but a hit depends on the request prefix and server-side cache state. Budget for uncached input as well.
Why does the calculator use the same token volume for different models?
It isolates listed price differences. It does not mean that two models use the same tokens or produce equivalent results for the same task. Record actual usage, retries and acceptance results to estimate task ROI.
When does Gemini 4 Argon’s introductory API price end?
Google lists November 30, 2026 as the last day of introductory pricing. The new listed rates start December 1. Recheck the official API price page when preparing a budget.
Compare cost per accepted task
Gemini 4 Argon’s cache discount can lower the input cost for repeated context. The final bill still depends on uncached input, thinking and output tokens, tools, retries and review time. Measure one repeatable task before deciding how much each model costs for an accepted result.
Model and workflow guides
Connect Qwen 3.8 27B to DSH
Connect local Qwen 3.8 27B to DSH: check the server, model ID, protocol and credentials, then test text, tools and image input separately.
Read →Model setup and costsCodex Costs: API Billing vs Subscription Usage
Understand Codex API billing, subscription limits and credits, with GPT-5.6 Sol vs GPT-5.5 rates and a clearly scoped token-cost example.
Read →Model setup and costsConnect the Grok API to DSH
Connect the Grok API to DSH: distinguish Grok from Groq, match credentials and protocol, and check independent requests, text and tools.
Read →Model setup and costsChoose a Gemini Model by Task and Cost
Choose Gemini by task, inputs, interface and API cost. Check promotion dates and model status, then verify what your DSH adapter supports.
Read →Model benchmarks and engineeringGemini 4 Argon Coding Benchmarks: Long Decode, Limits and Use Cases
Compare Google-published Gemini 4 Argon coding scores, its shared 1M-token window, long-decode limits, and the DSH model-catalog checks to make before choosing.
Read →Model setup and costsClaude Sonnet vs Opus: Which Should You Use?
Compare Claude Sonnet and Opus 5.5 by API rates, retries and review effort, then use the same coding task to decide whether an upgrade is worthwhile.
Read →Model interfaces and workflowsCan MiniMax H3 Work with DSH?
Learn how MiniMax H3 differs from M-series coding models, which API routes DSH uses, and what to verify before integrating a video asset.
Read →API credentials and troubleshootingKimi API Key Errors: Region, Model and Permissions
Fix Kimi API key setup errors by matching region and model ID, reading HTTP responses, and checking DSH or OpenChamber's actual configuration.
Read →Image editing and toolsAI Image Editing: Prompts, Masks and Review
Learn to define image edits, preserve important details, check masks and output files, and verify an editing tool before organizing it with DSH.
Read →